Deep DivesOpenAI's Habitat shows that production storage scales through event-loop telemetry, desynchronized background work, recovery-safe pooling, bounded query contracts, and only then a measured rewrite.
Sep 13, 2026 · 8 min read 
AI NewsA practical four-test framework for tracking whether Hugging Face remains open, multi-provider, and hardware-neutral under NVIDIA.
Sep 6, 2026 · 6 min read 
AI NewsAI coding agents need explicit context, permission, logging, and review boundaries as they gain access to real engineering workflows.
Aug 16, 2026 · 8 min read 
AI NewsClaude's new watermark can signal model processing, but it cannot prove authorship or rule out AI use when absent.
Aug 13, 2026 · 7 min read 
AI NewsOpenAI now offers an official ChatGPT desktop preview for Linux. Here is the supported distro matrix, install path, security model, and what is still missing.
Aug 13, 2026 · 6 min read 
AI NewsGPT-5.6-Cyber sharply reduces refusals for advanced authorized security work, but Daybreak Red demands isolation, approval, and tighter controls.
Aug 12, 2026 · 5 min read 
AI NewsNvidia released Nemotron 3.5 Lightning on August 11, 2026: an open 30B mixture-of-experts model with 3B active parameters, licensed under OpenMDW-1.1 with weights, training data and recipes included. It targets the execution layer of long-running agents rather than frontier reasoning, reaching 86% accuracy on PinchBench while completing 10,000 tasks 30% faster than Qwen3.6 35B, and up to 4x the output speed of similar-sized models. Speed comes from baked-in multi-token prediction plus DSpark and DFlash draft models, with NVFP4 and BF16 checkpoints. It runs on Jetson, RTX 5090 and DGX Spark via LM Studio, llama.cpp, Ollama and Unsloth, and ships alongside NeMo Switchyard for routing planning to frontier models and execution to Lightning.
Aug 12, 2026 · 6 min read 
AI NewsByteDance released Seedance 2.5 on July 31, 2026. It generates 30-second video clips with audio in a single pass, supports multi-turn extension, and accepts up to 30 images, 10 videos, and 10 audio files as reference per input. Google's Gemini Omni Flash currently caps output at 10 seconds and does not yet support audio reference uploads or scene extension in the Gemini API. Seedance 2.5 launched on Jimeng AI and Doubao Pro; BytePlus ModelArk published a Seedance 2.5 tutorial on August 7, 2026, but regional API availability should be verified before building a production dependency.
Aug 10, 2026 · 7 min read 
AI NewsMeta Superintelligence Labs released Muse Code, a beta terminal coding agent for macOS and Linux powered by the new Muse Spark 1.2 model, on August 5, 2026. Meta reported 82.9% on Terminal-Bench 2.1 but placed behind Claude Opus 5 on all three coding charts it published, and both figures come from Meta's own harness with no verified leaderboard entry. Meta's previous model published 80.0 and verified at 76.2% when the Terminal-Bench team ran it. The genuinely notable engineering is an append-only event log that makes runs replay-exact and restart-safe, plus persistent async background agents. The most consequential detail is pricing: a contributor tier at $0.10 per million input and $0.20 per million output tokens, 12.5x and 21x cheaper than standard, in exchange for Meta training on your prompts.
Aug 6, 2026 · 8 min read 
AI NewsDeepSeek upgraded its deepseek-v4-flash API to the 0731 public beta on July 31, 2026 — an API-only post-training update that leaves the 284B/13B MoE architecture, 1M context window and $0.14/$0.28 pricing untouched. Artificial Analysis measures a 10-point Intelligence Index jump to 50 and a GDPval-AA v2 rise from 1189 to 1559 Elo, with Cost per Task roughly 60% below GPT-5.6 Luna. Accuracy on AA-Omniscience is unchanged at 37%, and the 0731 weights are not open — only the April 24 checkpoint is on Hugging Face under MIT.
Aug 5, 2026 · 6 min read 
AI NewsAlibaba released Qwen3.8-Max on August 3, 2026, a 2.4-trillion-parameter mixture-of-experts model with a 1M-token context window, multimodal (text/image/video) input, and $2/$6 per-million-token pricing. Benchmarks are self-reported and lead on multimodal and agentic tasks while trailing the frontier on pure software engineering. Open weights for the flagship and a deployable 27B checkpoint are promised the following week.
Aug 4, 2026 · 4 min read 
AI NewsDeepSeek released V4 as two open-weight mixture-of-experts models: V4-Pro (1.6T total / 49B active) and V4-Flash (284B / 13B active), both with a 1M-token default context and 384K max output. A novel token-wise compression plus DeepSeek Sparse Attention (DSA) makes the long window affordable. API pricing is aggressive (V4-Flash $0.14/M input, $0.28/M output; V4-Pro $0.435/$0.87), and the old deepseek-chat and deepseek-reasoner endpoints were retired after July 24, 2026. Reported ~80.6% on SWE-bench Verified.
Aug 1, 2026 · 5 min read 
AI NewsPoolside released Laguna S 2.1 on July 21, 2026, a 118B-parameter Mixture-of-Experts coding model activating ~8B params per token, with a 1M-token context and a permissive OpenMDW-1.1 license. First-party benchmarks show 78.5% on SWE-Bench Multilingual, but independent verification is still pending. Day-one FP8/NVFP4/INT4 and GGUF builds make it genuinely self-hostable.
Jul 31, 2026 · 5 min read 
AI NewsFLUX 3, released July 23 2026, is Black Forest Labs' first multimodal model to generate video, audio, and robot actions from one set of weights, built on the Self-Flow method. FLUX 3 Video produces up to 20-second clips with native audio and led human-preference tests over Luma Ray 3.2 (93%) and Runway Gen-4.5 (77%), tying Seedance 2.0 and Gemini Omni Flash at 52%. Access is gated: video and action first, image next, open weights last.
Jul 28, 2026 · 5 min read 
AI NewsClaude Opus 5, released July 24, 2026, is Anthropic's new default model: near-Fable 5 capability at $5/$25 per million tokens (half Fable 5's price, flat vs Opus 4.8). It leads on Anthropic's own runs of Frontier-Bench, OSWorld 2.0, AutomationBench, ARC-AGI-3 and GDPval, but loses on DeepSWE, HLE, a legal benchmark and HealthBench. It posts Anthropic's lowest misalignment score (2.30), ships with no default data retention, and adds beta tool-swapping and safety-filter model routing.
Jul 26, 2026 · 7 min read 
AI NewsEtched, a startup building the transformer-only Sohu inference ASIC, has booked over $1 billion in contracts and reached a $5 billion valuation, with reports of new rounds valuing it up to $20 billion. Sohu hard-wires the transformer graph into silicon on TSMC N4P with 144GB HBM3E, and Etched claims an 8-chip server exceeds 500,000 Llama 70B tokens/sec. No independent benchmarks exist yet.
Jul 25, 2026 · 5 min read 
AI NewsMicrosoft is reportedly developing Project Perception, a multi-model AI security platform that routes vulnerability-scanning tasks across models from Microsoft, OpenAI, and Anthropic to reserve expensive frontier calls for high-value steps. Its pitch is matching Anthropic's Claude Mythos on capability while costing far less. Microsoft has not officially confirmed details, so the news should be treated as a credible report pending benchmarks.
Jul 21, 2026 · 5 min read 
AI NewsThinking Machines Lab, founded by ex-OpenAI CTO Mira Murati, released Inkling on July 15, 2026 — an open-weight mixture-of-experts model with 975B total parameters (41B active), trained on 45 trillion multimodal tokens. The company openly says it isn't the strongest model available; instead it's a customizable foundation enterprises fine-tune via the Tinker platform. The release doubles as an argument that owned, adaptable models beat rented one-size-fits-all APIs.
Jul 18, 2026 · 5 min read 
AI NewsMoonshot AI released Kimi K3 on July 16, 2026, a 2.8-trillion-parameter open Mixture-of-Experts model that activates 16 of 896 experts, ships native vision and a 1M-token context, and leads benchmarks like SWE Marathon, BrowseComp, and OmniDocBench while trailing Fable 5 and GPT-5.6 Sol overall. Weights release July 27 under a Modified MIT license.
Jul 17, 2026 · 5 min read 
AI NewsCognition released SWE-1.7 on July 8, 2026, a software-engineering model built by reinforcement-learning on top of Moonshot AI's Kimi K2.7 base and served through Cerebras at ~1,000 tokens/second inside the Devin agent. It scores 42.3% on FrontierCode 1.1 and 81.5% on Terminal-Bench 2.1, trailing Opus 4.8 by a few points at roughly $1.97 per task, positioning it as a near-frontier option at a fraction of frontier cost.
Jul 14, 2026 · 5 min read 
AI NewsMeta released Muse Spark 1.1 on July 9, 2026, opening its reasoning model to developers via a paid API priced at $1.25/M input and $4.25/M output tokens, undercutting Grok 4.5 and Anthropic's Opus. Meta claims wins over older rival models and Google's latest Gemini, but did not compare against the newest flagships, and a bigger model code-named Watermelon is still in training.
Jul 13, 2026 · 6 min read 
AI NewsGrok 4.5, released July 8, 2026, is xAI's coding-focused model. It ranks 4th on the Artificial Analysis Intelligence Index (score 54), wins SWE Marathon (29%), and prices at $2/$6 per million tokens with 4.2x better token efficiency than Opus 4.8. Not yet available in the EU.
Jul 12, 2026 · 5 min read 
AI NewsOpenAI made its three-tier GPT-5.6 family (Sol, Terra, Luna) generally available on July 9, 2026 after government safety review. Pricing runs from Luna at $1/$6 to Sol at $5/$30 per 1M tokens, with a Sol Fast option at $12.50/$75 on Cerebras. The release adds Programmatic Tool Calling in the Responses API (63.5% fewer tokens, 50.1% fewer turns) and longer prompt caching, but Sol's 64.6% on SWE-Bench Pro still trails Claude Mythos 5 (80.3%).
Jul 11, 2026 · 5 min read 
AI NewsOn July 6, 2026, OpenAI released GPT-Realtime-2.1 and GPT-Realtime-2.1-mini for the Realtime API. The headline change is reasoning in the low-cost mini tier, plus a 25% cut in p95 latency from better caching. The mini holds the prior gpt-realtime-mini price (0 audio in, 0 audio out per 1M) while the full model runs 2/4. Reasoning effort is configurable from minimal to xhigh.
Jul 8, 2026 · 5 min read 
AI NewsGoogle released Gemini 3.5 Flash on May 19, 2026, at Google I/O. The Flash-tier model beats Gemini 3.1 Pro on coding and agentic benchmarks (76.2% Terminal-Bench 2.1, 83.6% MCP Atlas, 1656 GDPval-AA Elo) while running 4x faster and costing $1.50/$9 per 1M tokens, 40% below 3.1 Pro. It trails Pro on academic reasoning (Humanity's Last Exam, ARC-AGI-2) and dense long-context recall. It powers Gemini Spark, Antigravity 2.0, and is now the default model for the Gemini app and AI Mode in Search.
Jul 7, 2026 · 5 min read 
AI NewsAnthropic launched Claude Science on June 30, 2026, an AI research workbench for Pro, Max, Team, and Enterprise users on macOS and Linux. A coordinating agent taps 60+ skills and connectors across genomics, proteomics, and cheminformatics, generates fully reproducible artifacts, manages HPC and Modal compute, and runs a reviewer agent that checks citations and calculations. Early users at the Allen Institute, UCSF, and Manifold Bio report large speedups. Anthropic is funding up to 50 AI for Science projects with up to $30,000 in credits each; applications close July 15, 2026.
Jul 6, 2026 · 5 min read 
AI NewsOpenAI unveiled Jalapeño, its first custom inference chip co-designed with Broadcom on TSMC 3nm. Built in a nine-month design cycle, the reticle-sized ASIC targets roughly 50% lower inference cost than current Nvidia GPUs, with deployment starting late 2026 and Microsoft reportedly taking 40% of the first run for Azure.
Jul 6, 2026 · 4 min read 
AI NewsClaude Fable 5, Anthropic's Mythos-class model, was suspended June 12, 2026 under a U.S. export-control directive and restored July 1 after Anthropic made security commitments. It leads coding benchmarks at 80.3% SWE-Bench Pro (vs 69.2% for Opus 4.8) and 29.3% FrontierCode. A grace window counts it toward 50% of weekly usage through July 7; credits billing follows.
Jul 3, 2026 · 5 min read 
AI NewsOn June 26, 2026, OpenAI previewed the GPT-5.6 series — Sol (flagship), Terra (balanced, 2x cheaper than GPT-5.5), and Luna (fastest, cheapest) — but restricted access to trusted partners at the US government's request due to the models' strong cybersecurity capabilities. OpenAI paired the release with its most robust layered safeguard stack and said it does not want government pre-release review to become the default.
Jul 2, 2026 · 6 min read 
AI NewsClaude Sonnet 5, released June 30, 2026, is Anthropic's most agentic mid-tier model. It beats Sonnet 4.6 on every published benchmark (63.2% SWE-bench Pro, 80.4% Terminal-Bench 2.1, 81.2% OSWorld) and edges Opus 4.8 on GDPval-AA v2 knowledge work. Intro pricing is /0 per million tokens through Aug 31, 2026, then /5. A new tokenizer can raise token counts up to 1.35x, and xhigh effort can cost more than Opus 4.8.
Jul 1, 2026 · 5 min read 
AI NewsGrok 4.3 is generally available on Amazon Bedrock with a 1M-token context window, $1.25/$2.50 pricing, and a top hallucination-rate score.
Jun 29, 2026 · 4 min read 
AI NewsZ.AI released GLM-5.2 on June 16, 2026: a 753B-parameter MoE model under an MIT license with a 1M-token context. It tops open-weight coding benchmarks, beating GPT-5.5 on SWE-bench Pro, FrontierSWE and PostTrainBench at roughly one-sixth the cost.
Jun 26, 2026 · 5 min read 
AI NewsMicrosoft unveiled MAI-Thinking-1 at Build 2026, its first reasoning model trained in-house without distillation. The 35B-active, ~1T-total MoE has a 256k context window, scores 97.0% on AIME 2025 and matches Claude Opus 4.6 on SWE-Bench Pro. It's in private preview on Microsoft Foundry.
Jun 23, 2026 · 5 min read 
AI NewsMistral AI used its May 2026 AI Now Summit to pivot toward industrial engineering, announcing a physics-AI stack, the Emmi acquisition, partnerships with Airbus, BMW (crash simulation) and ASML, the unified Vibe agent, and a 10 MW Les Ulis inference data center opening Q3 2026.
Jun 19, 2026 · 5 min read 
AI NewsOn June 3, 2026, Meta made Meta Business Agent globally available to businesses of all sizes across WhatsApp, Messenger, and Instagram. The agent answers questions, recommends catalog products, books appointments, qualifies leads, and closes sales, with human handoff. A new Business Agent Platform connects to hundreds of systems like Shopify, Zendesk, and Shopee. It's free to start, with token-based pricing for larger businesses.
Jun 17, 2026 · 5 min read 
AI NewsMiniMax M3 is an open-weight model pairing a 1M-token context and revived sparse attention with frontier coding benchmarks at 15x lower cost than Claude Opus 4.7.
Jun 16, 2026 · 6 min read 
AI NewsOn June 1, 2026, Anthropic confidentially filed a draft S-1 with the SEC at a roughly $965B valuation, backed by a $65B raise and a ~$47B May run-rate. OpenAI followed on June 8. Both target public listings as soon as fall 2026.
Jun 15, 2026 · 5 min read 
AI NewsMoonshot AI's Kimi K2.7-Code is an open-weights, OpenAI-compatible coding model (1T-param MoE, 32B active, 256K context) claiming a 30% cut in reasoning tokens and a narrow win over Claude Opus 4.8. But all published benchmarks are Moonshot's own proprietary suites, with no independent results yet, so the efficiency claims remain unverified.
Jun 14, 2026 · 5 min read 
AI NewsAt WWDC 2026, Apple unveiled a rebuilt Siri powered by a custom, Apple-tuned Google Gemini model—reportedly a 1.2-trillion-parameter mixture-of-experts system costing roughly $1 billion a year. On-device Apple Silicon models handle quick private tasks, while complex reasoning routes to the Gemini model inside Apple's Private Cloud Compute, with a contract barring Google from training on Apple user data.
Jun 11, 2026 · 5 min read 
AI NewsGoogle released Gemma 4 12B on June 3, 2026, a multimodal open model with an encoder-free architecture that feeds vision and audio directly into the LLM backbone. It runs locally on 16GB of memory, approaches the 26B MoE on benchmarks, uses Multi-Token Prediction drafters for low latency, and ships under Apache 2.0 with broad tooling support.
Jun 9, 2026 · 5 min read 
AI NewsMicrosoft launched MAI-Code-1-Flash on June 2, 2026, a lightweight, agentic coding model built end-to-end in-house and rolling out to GitHub Copilot users in VS Code. It outperforms Claude Haiku 4.5 across four coding benchmarks (including 51.2% vs 35.2% on SWE-Bench Pro) while using up to 60% fewer tokens, signaling Microsoft's push for AI independence from OpenAI.
Jun 6, 2026 · 5 min read 
AI NewsOn May 22, 2026, DeepSeek made its 75% promotional discount on V4-Pro permanent rather than letting it expire May 31. New permanent rates: $0.435/M input, $0.87/M output, $0.003625/M cache hit. That puts V4-Pro output roughly 34x cheaper than GPT-5.5 and 17x cheaper than Claude Opus 4.7, while landing within 3-7 points on coding and reasoning benchmarks. The underrated detail is the cache-hit price, which can cut input cost ~88% for agents with stable prefixes. Teams should re-run their build math and route the easy majority of traffic to V4-Pro.
Jun 1, 2026 · 5 min read 
AI NewsAnthropic released Claude Opus 4.8 on May 28, 2026, 41 days after Opus 4.7. It scores 69.2% on SWE-Bench Pro, emphasizes calibrated honesty and longer autonomy, adds Dynamic Workflows for hundreds of parallel subagents, runs fast mode ~2.5x quicker, and holds pricing flat from 4.7.
May 30, 2026 · 4 min read 
ReviewsVivago Video Agent uses AI directors to generate 1-minute 1080p videos from a single story line.
May 29, 2026 · 4 min read 
AI NewsGemini 3.5 Flash outperforms the Pro tier on agent benchmarks with superior speed and efficiency.
May 28, 2026 · 5 min read 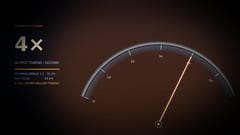
AI NewsGemini Spark is Google's 24/7 agent that continues working even when your laptop is closed.
May 27, 2026 · 6 min read 
AI NewsAlibaba's Qwen3.7-Max agent achieved a 35-hour autonomous run, setting new performance and cost benchmarks.
May 25, 2026 · 5 min read 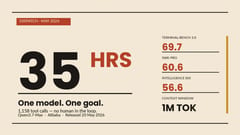
ReviewsPollyReach provides AI agents with real phone numbers, enabling multi-language calls and skill distribution.
May 20, 2026 · 7 min read 
AI NewsGoogle's Gemini Intelligence brings OS-level AI to Android, transforming how devices integrate artificial intelligence.
May 19, 2026 · 5 min read 
AI NewsAnthropic's 'Claude for Small Business' integrates AI into SMB tools like QuickBooks, targeting 36M businesses.
May 17, 2026 · 6 min read 
AI NewsSubQ is a new 12M-token subquadratic LLM claiming massive context and low compute, sparking debate among researchers.
May 16, 2026 · 5 min read 
AI NewsLightfield is an AI-native CRM by Tome's founders, using agents to automate sales tasks like prospecting and coaching.
May 15, 2026 · 5 min read 
AI NewsOpenAI's GPT-Realtime-2 voice model now boasts GPT-5 reasoning and advanced features.
May 14, 2026 · 6 min read 
AI NewsAnthropic's Claude agents now 'dream' to learn and improve task completion overnight.
May 13, 2026 · 5 min read 
AI NewsMoonshot's Kimi K2.6, an open-weights model, surpasses GPT-5.4 on SWE-Bench Pro.
May 12, 2026 · 6 min read 
AI NewsOpenAI's Codex 3.0 offers an autonomous build-test-debug loop powered by GPT-5.5.
May 11, 2026 · 5 min read 
AI NewsOpenAI's GPT-5.5-Cyber, a less-restricted model, is now available for vetted cyber defenders.
May 8, 2026 · 6 min read 
AI NewsAnthropic launches a $1.5B AI services firm, directly challenging big consulting.
May 7, 2026 · 6 min read 
AI NewsDeepMind's Vision Banana outperforms leading models, suggesting generation is key for vision pretraining.
May 6, 2026 · 4 min read 
AI NewsOpenAI's GPT-5.5 is a fully retrained model, focusing on agentic computer use, not just benchmarks.
May 5, 2026 · 5 min read 
AI NewsMistral Medium 3.5 is a powerful 128B open-weight model capable of opening GitHub pull requests.
May 4, 2026 · 7 min read 
AI NewsMicrosoft Agent 365 offers a control plane to observe, govern, and secure all your AI agents.
May 2, 2026 · 6 min read 
AI NewsDeepSeek V4 Pro is a top 1.6T open-weights model for agents, but has a high hallucination rate.
Apr 29, 2026 · 5 min read 
AI NewsCoinbase launched AI agents modeled on Fred Ehrsam and Balaji Srinivasan in Slack and email.
Apr 21, 2026 · 5 min read 
AI NewsOpenAI's Agents SDK now features sandboxes, built-in providers, and durable state for long-horizon agents.
Apr 20, 2026 · 5 min read 
AI NewsAnthropic's Claude Opus 4.7 excels on SWE-bench Pro with enhanced vision and new features.
Apr 19, 2026 · 6 min read 
AI NewsMicrosoft's MAI-Transcribe-1 beats Whisper with 3.8% WER and lower costs, signaling independence from OpenAI.
Apr 17, 2026 · 6 min read 
AI NewsAlibaba's Qwen 3.6 Plus Preview surpasses Claude Opus on agent tasks with impressive speed and context.
Apr 15, 2026 · 5 min read 
AI NewsFigma now enables AI agents to design and modify directly on its canvas, leveraging your design system.
Apr 15, 2026 · 4 min read 
AI NewsAtlassian Remix brings AI visuals and MCP agents to Confluence, transforming pages into dynamic content.
Apr 10, 2026 · 4 min read 
AI NewsMeta Muse Spark, from Superintelligence Labs, marks a strategic AI reset with top benchmarks and medical reasoning.
Apr 9, 2026 · 5 min read 
AI NewsBluesky's Attie AI feed builder, powered by Claude, was blocked by 125,000 users quickly.
Apr 8, 2026 · 4 min read 
ReviewsMindsDB Anton is an open-source BI agent that replaces dashboards by answering questions in plain English.
Apr 8, 2026 · 4 min read 
AI NewsDenovo's AI platform turns a business idea into a fully running startup in just eight minutes.
Apr 3, 2026 · 5 min read 
AI NewsZ.ai's GLM-5V-Turbo vision model converts screenshots directly into executable code efficiently.
Apr 3, 2026 · 4 min read 
AI NewsTobira.ai is an AI agent network where bots find clients, partners, and investors for you.
Apr 2, 2026 · 5 min read 
AI NewsGoogle Stitch 2.0, a free AI design tool, topped Product Hunt with new vibe design and voice canvas.
Apr 2, 2026 · 4 min read 
AI NewsEli Lilly's LillyPod, a 9,000-petaflop AI supercomputer, is making big bets on drug discovery.
Apr 1, 2026 · 4 min read 
AI NewsNVIDIA's Nemotron 3 Super, a hybrid architecture, delivers 5x throughput and top agentic benchmarks.
Mar 31, 2026 · 4 min read 
Open SourceAlibaba's Qwen 3.5 Small, a 9B multimodal AI, surprisingly beats models 13x its size.
Mar 29, 2026 · 5 min read 
AI NewsOpenAI's GPT-5.4, with five variants and expert-level computer use, is reshaping the AI market.
Mar 29, 2026 · 5 min read